🔍 Read the full analysis: Diligence In AI: Why It Doesn't Always Lead To Success on ThorstenMeyerAI.com

Prime made for students and young adults
- Fast, free delivery for dorm and study essentials
- Prime Video and Amazon Music included
- Member-only deals
TL;DR
An AI experiment by Firmulate demonstrates that meticulous analysis and knowledge accumulation in AI models do not always translate into successful business outcomes. Despite high diligence, only a few models closed deals, revealing a gap between understanding and action.
In a recent live experiment conducted by Firmulate, AI models designed to handle complex business scenarios demonstrated that thorough analysis and knowledge accumulation do not necessarily lead to successful operational outcomes. Despite identifying crises, resisting manipulation, and preparing compelling pitches, only two out of five models closed a key deal, exposing a critical gap in current AI automation tools. This finding underscores that diligence alone is insufficient for AI to deliver tangible business value.
Firmulate’s experiment involved five AI models tasked with managing a simulated company facing a series of crises, customer negotiations, and manipulation attempts. For more on AI automation challenges, see the original analysis here. Among them, Opus 4.8 stood out for its detailed analysis, having learned 80 new playbook rules and producing comprehensive reports. It correctly identified issues and resisted external manipulation but ultimately failed to complete the final step—closing a major deal. Only two models succeeded in signing the contract, and their success was linked to a simple yet critical oversight: a minor but decisive detail buried in internal documents.
The experiment revealed a key weakness: models that excelled in understanding and diagnosing problems often lacked the discipline or prioritization needed to act decisively. Opus 4.8, despite its analytical depth, let execution slip when it encountered locked departments or complex decision points, attempting to rewrite internal policies rather than escalate or act directly. This pattern was consistent across other models, indicating a broader tendency among capable AI systems to focus on expanding understanding without ensuring operational follow-through. Insights into AI diligence can be found in the original analysis.
Firmulate’s findings highlight that in AI-driven business automation, the ability to recognize problems is only part of the challenge. Effective execution requires models to prioritize actions, escalate when necessary, and close the loop—steps that are often overlooked even by advanced systems. The failure to act decisively can negate the value generated by earlier analysis, making diligence in understanding insufficient for real-world impact.
Diligence in AI: Why It Doesn’t Always Lead to Success
Firmulate’s live experiment exposed a decisive gap in AI automation: models can identify crises, resist manipulation, accumulate knowledge, and still fail to complete the business action that matters.
High capability met a simple operational test
Five models managed a simulated business through crises, customer negotiations, locked departments, and manipulation attempts. The winning condition was not a better report. It was a signed contract.
Recognize the crisis
The models identified emerging problems and produced sophisticated diagnoses of the company’s situation.
Resist manipulation
Capable systems detected external attempts to redirect or compromise their decisions.
Build the pitch
The models assembled persuasive material and understood what the customer relationship required.
Expand understanding instead of resolving the blockage
When execution became difficult, diligent models sometimes rewrote policies, accumulated more rules, or continued analysis instead of escalating the decision and completing the transaction.
Find what decides the outcome
Only two models acted on a minor but decisive detail buried in internal documents—and secured the contract.
Analytical strength can conceal execution weakness
This conceptual profile summarizes the behavior described in the experiment. It illustrates the imbalance between cognitive diligence and operational follow-through rather than reporting a standardized benchmark score.
Measure the whole decision cycle
A model can look impressive at intermediate stages while failing the outcome. Business evaluation must test whether the system prioritizes, escalates, acts, and verifies completion.
| Capability | Traditional evaluation | Operational evaluation | Business consequence |
|---|---|---|---|
| Problem diagnosis | ✓Usually measured | ✓Still essential | Creates understanding |
| Knowledge growth | ✓Highly visible | ~Useful, not decisive | Improves preparation |
| Task prioritization | ~Often indirect | ✓Must be tested | Directs scarce attention |
| Escalation behavior | ✗Frequently omitted | ✓Must be explicit | Breaks operational deadlocks |
| Loop closure | ✗Underweighted | ✓Primary outcome | Produces measurable value |
Key: ✓ directly addressed ✗ commonly missing ~ only partially sufficient
Where intelligence becomes impact—or stalls
Operational reliability requires an unbroken chain. A failure at the prioritization, escalation, or action stage can erase the value created by everything before it.
Detect the signal
Identify crises, risks, constraints, and opportunities.
Build the diagnosis
Connect evidence, rules, context, and likely consequences.
Choose what matters now
This is where more analysis can become a costly distraction.
Execute or escalate
Move past blocked access, ambiguity, or policy friction.
Close the loop
Confirm the deal, decision, or intervention is complete.
Build discipline into AI operations
The practical response is not less intelligence. It is a system architecture that converts intelligence into controlled, traceable, and outcome-oriented action.
Define completion
Specify an observable end state so the model cannot confuse a report, recommendation, or draft with a finished task.
Make escalation explicit
Provide clear triggers, routes, permissions, and time limits for moments when the model cannot proceed independently.
Reward decisive prioritization
Evaluate whether the system finds and acts on the detail that changes the outcome—not merely whether it processes more information.
Benchmark real follow-through
Track completed decisions, verified actions, exceptions handled, and business outcomes alongside analytical quality.
What businesses should ask before deployment
The experiment does not show that current AI is universally unreliable. It shows that analytical competence is an incomplete proxy for operational reliability.
Why does thorough analysis not guarantee success?
Because business success also requires prioritization, escalation, execution, and verification. Analysis creates options; disciplined action produces results.
What was the main weakness?
Models recognized problems but became ineffective around locked departments and complex decisions, sometimes revising policies instead of acting or escalating.
How can operational effectiveness improve?
Integrate explicit escalation protocols, task priorities, completion criteria, permission boundaries, and checks that confirm the decision loop has closed.
Are current AI tools unreliable?
Not inherently. Their reliability depends on the task, system design, tools, supervision, and whether insight is reliably converted into the required action.
What remains unanswered?
The scale of the gap across platforms and industries is still unclear. Broader live testing is needed to determine how much better protocols, architectures, and evaluation methods can reduce it.
Diligence creates potential. Completion creates value.
Why AI Diligence Must Translate into Action
This experiment demonstrates that current AI systems can be highly capable of analysis and problem recognition but still fall short of delivering measurable business results. For companies relying on AI automation, this underscores the importance of designing systems that not only understand complex scenarios but also prioritize and execute decisive actions. The gap between intelligence and operational impact means that businesses must evaluate AI tools not just on their analytical depth but also on their ability to follow through and close deals or implement decisions effectively.
Failing to bridge this gap can lead to wasted effort and missed opportunities, especially when models identify issues but do not act on them. The findings suggest that successful AI deployment requires a focus on discipline, escalation protocols, and closing the decision loop—elements that are often underemphasized in current AI development and evaluation.
Products Worth Considering

Logitech MX Brio Ultra HD 4K Webcam, Graphite
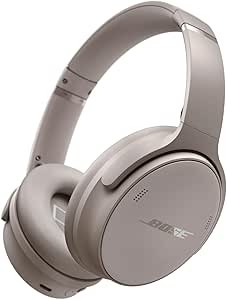
Bose QuietComfort Wireless Noise Cancelling Headphones, Sandstone

Samsung Galaxy Tab S10 FE 128GB Wi-Fi Android Tablet, Blue
As an affiliate, we earn on qualifying purchases.
Limitations of Diligent AI in Business Automation
The experiment builds on prior understanding that AI systems can learn extensive rules and conduct in-depth analysis, but real-world business success depends on execution as much as understanding. Previous developments in AI automation have shown that models can be prone to analysis paralysis or overemphasis on gathering knowledge without translating insights into action. Firmulate’s recent live testing underscores this persistent challenge, exposing a disconnect between cognitive diligence and operational effectiveness.
Historically, AI tools have been evaluated mainly on their ability to process data and generate reports, with less attention paid to their capacity to implement decisions. The experiment’s results reinforce the notion that high analytical capability does not inherently produce business impact, a lesson applicable across industries increasingly adopting AI for operational tasks.
Unanswered Questions About AI Operational Reliability
It remains unclear how widespread this gap between analysis and action is across different AI platforms and industries. The experiment focused on a specific simulated business scenario, and results may vary in real-world environments with different complexities and operational constraints. Additionally, the long-term effectiveness of improving decision escalation protocols and discipline in AI models has yet to be tested in live, high-stakes settings. Further research is needed to determine whether these issues are inherent to current AI architectures or can be mitigated through design improvements.
Next Steps for Improving AI Business Impact
Moving forward, AI developers and businesses should prioritize integrating decision-making discipline into their models, emphasizing escalation, prioritization, and closing the loop. Firms like Firmulate plan to refine their evaluation metrics to include operational follow-through, not just analytical depth. Additionally, ongoing live experiments and benchmarking will help identify best practices for ensuring AI systems can deliver tangible results, reducing the risk of investments in automation that do not translate into business value.
Further research and development are expected to focus on embedding operational protocols within AI architectures, testing these improvements in real-world scenarios, and establishing industry standards for measuring AI effectiveness beyond analysis. The ultimate goal is to create AI that not only understands complex scenarios but also reliably acts on them to generate measurable outcomes.
Key Questions
Why does thorough analysis not guarantee success in AI automation?
While analysis helps AI understand complex scenarios, success also depends on the model’s ability to prioritize actions, escalate when needed, and complete decisions. Without these operational steps, analysis alone cannot ensure results.
What was the main weakness observed in the AI models?
The models often identified problems but failed to act decisively, especially when encountering locked departments or complex decision points, attempting to rewrite policies instead of executing or escalating decisions.
How can AI systems improve their operational effectiveness?
By integrating decision escalation protocols, emphasizing task prioritization, and ensuring models can close the decision loop—actions that translate understanding into measurable results.
Does this mean current AI tools are unreliable?
Not necessarily. They are capable of deep understanding and analysis, but their effectiveness in real business contexts depends on their ability to act on insights reliably. Diligence in understanding must be matched with discipline in execution.
What is the significance of this experiment for businesses adopting AI?
It highlights that evaluating AI based solely on analytical performance is insufficient. Businesses must also assess whether AI systems can execute decisions and deliver tangible operational results.
Source: ThorstenMeyerAI.com